Last reviewed: 30 October 2026 ·
To optimise AI SEO content for both traditional search and AI answer engines, you need a single editorial process: start with a specific question your audience actually asks, answer it directly in the first 2-3 sentences, then support it with verifiable facts and named sources. Google's ranking signals and the citation signals used by AI Overviews, ChatGPT and Perplexity overlap heavily: both reward specificity, genuine expertise and self-contained answers over generic summaries. The risk with AI-assisted content isn't the production method; it's skipping the process that makes the content worth citing at all.
Quick facts
- Google's spam policies target low-quality scaled content regardless of production method, not AI-written content as a category
- AI answer engines cite pages that carry verifiable facts, named sources and self-contained answers, the same signals that drive traditional rankings
- A content pipeline without editorial and data layers upstream produces volume that still doesn't rank or get cited
- The Verqos content engine saves hundreds of hours per week (as at 14 October 2026), but only because the process was designed before the volume was added
- Toro's automated agents run 24/7 across its own businesses (as at 14 October 2026), handling structured data, syncing and publishing tasks that would otherwise block editorial work
What do SEO and AI answer engines actually have in common?
More than most people expect. Both reward content that answers a specific question directly, uses verifiable facts with named sources, and signals genuine knowledge. Google's E-E-A-T framework (Experience, Expertise, Authoritativeness and Trustworthiness) and the citation behaviour of AI answer engines converge on the same thing: a page that a knowledgeable person could quote with confidence.
Where they diverge is in how they surface content. Google uses links, crawl frequency and click signals. AI answer engines pull from indexed pages but weight self-contained answers more heavily, because the model needs a sentence it can reproduce without context. That means the format matters more than it used to. A buried answer, even a correct one, is hard for a model to quote accurately.
So the first step in building AI SEO content that works for both channels is not choosing between them. It's writing so that your answer appears in the first paragraph, is specific enough to be verifiable, and is not dependent on the paragraphs around it for meaning.
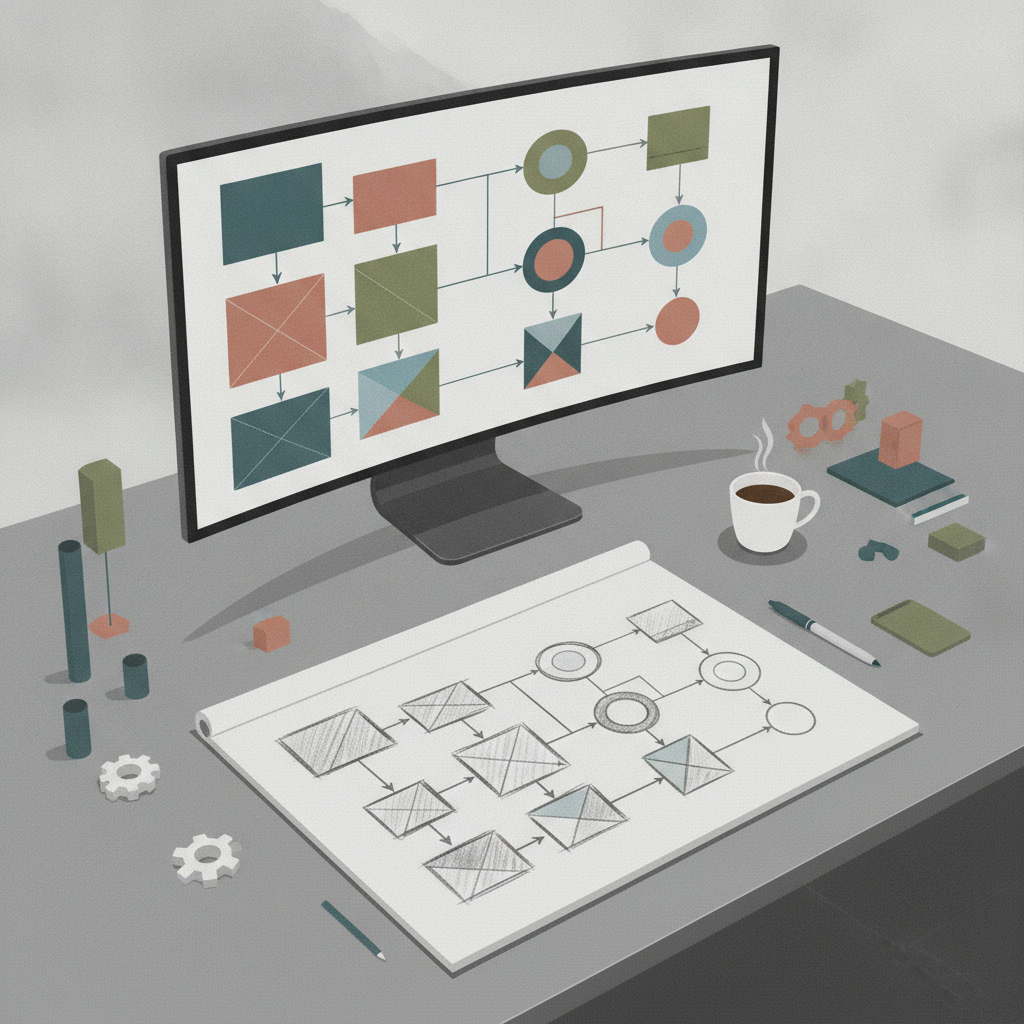
Two content pipelines compared
Why do most AI content pipelines fail to rank or get cited?
The pattern is consistent. A team gets access to an LLM, picks a list of target keywords, and starts generating articles. Volume goes up fast. Rankings don't follow, and AI citations don't appear either. The pipeline wasn't the problem. The missing layer was editorial: someone deciding what the content needs to contain that doesn't already exist on a hundred other pages.
Generic AI output is a competent summary of what's already indexed. It will compete with pages that have been indexed longer, have more links and carry original data. It will lose. The fix is not better prompts. It's giving the model something proprietary to work with: your own data, your customers' real questions, observations from your own business.
This is the lean-before-agents principle I apply before building any content pipeline. Remove the waste in the editorial process first. Identify what your content is missing that makes it genuinely useful. Then automate the production of that, not the production of generic summaries at scale.
At TrustedVillas, the sync pipeline processes data from 63,000+ properties (as at 14 October 2026). That's the kind of proprietary data that makes a page worth citing: specific, verifiable, and not available on a competitor's site. The editorial layer decides how to surface it. The agents handle the production and structured data tasks that run 24/7 (as at 14 October 2026) so the editorial team isn't blocked by repetitive work.
What does the process actually look like?
Here's how I structure content pipelines for AI SEO content that serves both channels.
1. Start with a single question, not a keyword. "Best campsites in the UK" is a keyword. "What campsites in the UK allow dogs on the beach?" is a question. Questions map to intent. A page built around a real question has a clear answer, which means it has something to cite.
2. Write the direct answer first. Two to three sentences that fully answer the question before you expand on it. This is the text an AI engine would quote. If it doesn't stand alone, rewrite it until it does. This is also the text Google's snippet algorithm looks at.
3. Add proprietary data or a named source. A stat from your own platform, a study you can link by name, an observation from your own customers. Campercation's live map covers 25,000+ stopovers (as at 14 October 2026). That's a specific, verifiable number that appears nowhere else and makes a page about UK wild camping genuinely citable.
4. Structure for scannability and extraction. H2 headings phrased as questions. Bullet lists for steps or comparisons. Tables where you're comparing options. FAQ blocks at the end with FAQPage schema. Each of these helps both a Google crawler and a language model find the relevant answer quickly.
5. Add editorial review, not just proofreading. Someone who knows the subject checks whether the answer is accurate, whether the source is credible, and whether there's anything the page claims that can't be verified. This is the step most AI content pipelines skip. It's also the step that determines whether the content passes E-E-A-T signals or fails them.
6. Automate the repeatable parts. Structured data generation, internal linking, image alt text, schema markup, publishing to CMS. These are the tasks that should run on agents. The Verqos content engine saves hundreds of hours per week (as at 14 October 2026) by handling exactly these tasks, not by replacing the editorial judgment about what to write.
Get the Agentic Playbook to see how this pipeline is structured end-to-end, including the agent tasks that run automatically and the editorial checkpoints that don't.What does good structure look like for AI citation specifically?
AI answer engines quote pages that are easy to extract from. That means:
- Direct answers at the top. The model doesn't scroll. If your answer is in paragraph seven, it won't be quoted.
- FAQ blocks. FAQPage schema tells a crawler these are self-contained question-and-answer pairs. Most AI overview citations come from FAQ blocks or opening paragraphs.
- Named, linkable sources. A claim backed by a named source is more citable than the same claim with no attribution. "According to [Publisher], [report name] ([year])" is the format to use.
- Consistent entity facts. Your business name, location, service description and contact details should appear identically across every page. Inconsistent entity signals make it harder for a model to build a coherent picture of who you are.
- Clean crawlability. AI crawlers need to reach and render your pages. On toro-solutions.com, the robots.txt explicitly allows GPTBot, ClaudeBot, PerplexityBot, Google-Extended and the other named AI crawlers. If your robots.txt blocks them, none of the above matters.
These signals overlap almost entirely with what makes a page strong for traditional SEO. That's the point. You're not building two content strategies. You're building one that's specific enough, structured enough and credible enough to satisfy both.
How does this connect to a GTM engineering approach?
Most businesses treat content as a marketing output. A GTM engineering approach treats it as a system: inputs (editorial decisions, data sources, audience questions), processes (drafting, review, structured data, publishing), and outputs (rankings, citations, leads). Each part of that system can be measured and improved separately.
The GTM engineering work I do with clients usually starts by mapping that system and finding where the waste is. Often it's in the brief: nobody has defined what a piece of content needs to contain to be genuinely useful. Often it's in the review step: content goes straight from AI draft to publish with no check on accuracy or source quality. And often it's in the structure: pages that answer a question buried in prose rather than a direct opening paragraph.
Fixing those things before scaling the pipeline is what determines whether volume produces results or just produces more content that doesn't rank. If you're building or rebuilding a content system, the GTM engineering framework is where I'd start: map the process, cut the waste, then automate what remains.
If you want to see how this applies to your specific content operation, the GTM teardown is the fastest way to identify where the process is breaking down and which steps are worth automating.
Frequently asked questions
Is AI-generated content bad for SEO?
Not inherently. Google's guidance judges content on quality and usefulness, not on how it was produced. AI-generated content that carries original data, editorial review and genuine expertise can rank well. The problem is that most AI content pipelines skip those steps, producing generic summaries that compete poorly against established pages. The production method is not the risk; the missing editorial process is.
Do AI answer engines like ChatGPT and Perplexity cite the same pages that rank on Google?
Often, yes. AI answer engines tend to cite pages that are already indexed, carry verifiable facts with named sources, and have direct answers near the top. These are the same signals Google rewards. A page built to rank well on Google, using specific data and clear structure, is also more likely to be quoted in an AI Overview or a Perplexity response. They're not separate targets.
How do I make my content more citable by AI engines?
Answer the question directly in the first two to three sentences. Use named, linkable sources for any factual claims. Add an FAQ block with FAQPage schema. Keep entity facts (business name, location, services) consistent across every page. Make sure your robots.txt allows the AI crawlers by name. None of these require a different content strategy; they require being more specific and structured than most content currently is.
What is AI SEO content and how is it different from regular SEO content?
AI SEO content refers to content built to perform in both traditional search rankings and AI answer engines like ChatGPT, Perplexity and Google AI Overviews. The principles are largely the same: specific answers, verifiable facts, structured formatting. The main difference is that AI engines weight self-contained, quotable answers more heavily, so the opening paragraph and FAQ structure matter more than they did in traditional SEO alone.
How do I scale content production without losing quality?
Build the editorial layer first: define what each piece needs to contain, what sources it draws on, and who reviews it for accuracy. Then automate the repeatable tasks: structured data generation, internal linking, schema markup, CMS publishing. The Verqos content engine follows this pattern, saving hundreds of hours per week (as at 14 October 2026) on production tasks while keeping editorial decisions in human hands.
What's the first thing to fix in a content pipeline that isn't producing results?
Check whether the content answers a specific question directly in the opening paragraph. If the answer is buried, scattered or generic, no amount of additional volume will fix the underlying problem. The second thing to check is whether each piece contains something verifiable and proprietary: original data, a named source, or an observation that can't be found on a competitor's page. Those two gaps account for most underperforming content pipelines.